Pepitedata
  • Home
  • Services
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

Local LLM

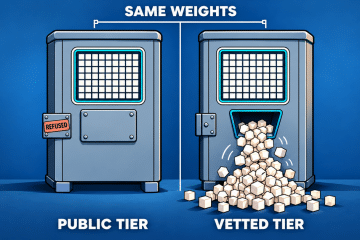
Cartoon of identical model cabinets: the public tier has a refused output, while the vetted tier releases a cascade of cubes under SAME WEIGHTS.
AI

After Coldcard: AI Security Depends on Access

The Bitcoin Red Team campaign after Coldcard exposed a dependency beyond model capability: usable access. Separate self-reported findings from confirmed vulnerabilities, then test safeguards, data controls and fallback workflows.
By Julien Laurenceau, 3 months2026-08-07 ago
A large layered model transfers a signal to a smaller model across a brighter slate background.
AI

How Big Models Teach Small Models, and Why It Looks Like School

Knowledge distillation trains a student using a teacher’s examples, output scores or internal features. Compare the access each method needs, then evaluate quality, unwanted behavior, serving performance and full lifecycle cost.

By Julien Laurenceau, 3 months2026-08-06 ago
A locally controlled GGUF model cartridge with a key and a reminder to test the answer
AI

Local LLMs, Political Bias, and Why llama.cpp Still Matters

Local inference gives control over weights and configuration, not a guarantee of political neutrality. A practical guide to evaluating framing, sizing KV memory and enforcing hybrid routing boundaries.

By Julien Laurenceau, 3 months2026-08-02 ago
AI

Distilling frontier reasoning into a local model: what actually works

A small coding model mocked on r/LocalLLM is actually a clean case of execution-verified distillation. Here is how the method works, when distilling a frontier model into a cheap local one pays off, and the three things the hype leaves out.

By Julien Laurenceau, 4 months2026-06-22 ago
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle