Pepitedata
  • Home
  • Services
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

AI

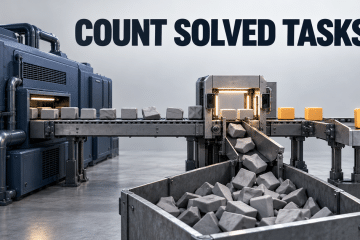
An industrial model-output line diverts failed tasks into a reject bin while verified amber tasks reach the finished-work tray.
AI

AI Infrastructure and SRE: Running Models in Production

A field guide to running AI in production: the supply chain as a dependency, quiet failure as the default mode, the verification gate as the method, and cost per correctly solved task as the metric.
By Julien Laurenceau, 4 weeks2026-09-30 ago
A navy vending machine labeled GLM 5.3 FLASH and FREE on a cream background, with a pipe from its back feeding a tank labeled PROMPT LOGS
AI

Your AI Supply Chain Is a Production Dependency. Audit It Like One.

Two movements meet: AI is getting production responsibilities, and production data is flowing through AI. Anthropic’s September report, malicious routers, training data provenance and model drift show what to verify before an AI reaches production.

By Julien Laurenceau, 1 month2026-09-12 ago
A sealed source-code box above an application preview, supported by CS and writing books
AI

Vibe Coding, CS Knowledge, and DHH’s Claim

A study of 100 students linked both CS knowledge and writing to vibe coding performance. I unpack the statistics, DHH’s claim and a practical way to test agent workflows.

By Julien Laurenceau, 2 months2026-09-06 ago
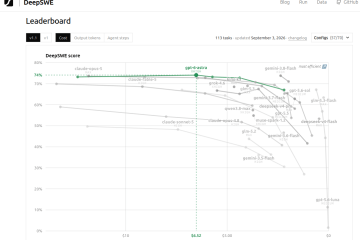
DeepSWE leaderboard: DeepSWE score against average cost per task for 113 tasks, with the cost-performance frontier highlighted and GPT-6-Astra XHIGH at .52 per task
AI

Efficiency Is Not Raw Power: Meet GPT-6-Astra and the DeepSWE Reality

GPT-6-Astra XHIGH sits alone on the DeepSWE cost-performance frontier, and an older model beats a flagship tier. Follow-up: DeepSeek V4.1 Flash hits 98% of Astra’s score at 1.4% of the cost.

By Julien Laurenceau, 2 months2026-09-06 ago
GPU rack with ten unbroken luminous conduits running to ten separate terminal screens, illustrating concurrent AI streaming sessions
AI

Real-Time AI Streaming Is a Product Trend, Not a Benchmark

AI products moved from the answer arrives to the answer flows. What streaming inference changes in capacity planning: TTFT, token throughput, concurrent streams.

By Julien Laurenceau, 2 months2026-09-01 ago
A well-built industrial staircase ends at a blank wall, illustrating an implementation that misses the intended outcome
AI

DHH on AI Coding: Expertise, Habits and Judgment

DHH’s account of AI coding raises a workflow question, not a universal ranking of developers. I separate requirements from implementation preferences and set out a practical review process.

By Julien Laurenceau, 2 months2026-08-30 ago
Unlabelled inference module under an inspection light on an engineering test bench
AI

Ox Alpha Review: Test a Free AI Model Before Production

Ox Alpha is a free anonymous-provider preview on OpenRouter. I explain how I would test task quality, agent reliability, cost, privacy, and fallback readiness before production use.

By Julien Laurenceau, 2 months2026-08-24 ago
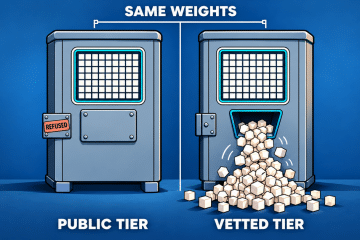
Cartoon of identical model cabinets: the public tier has a refused output, while the vetted tier releases a cascade of cubes under SAME WEIGHTS.
AI

After Coldcard: AI Security Depends on Access

The Bitcoin Red Team campaign after Coldcard exposed a dependency beyond model capability: usable access. Separate self-reported findings from confirmed vulnerabilities, then test safeguards, data controls and fallback workflows.

By Julien Laurenceau, 3 months2026-08-07 ago
A large layered model transfers a signal to a smaller model across a brighter slate background.
AI

How Big Models Teach Small Models, and Why It Looks Like School

Knowledge distillation trains a student using a teacher’s examples, output scores or internal features. Compare the access each method needs, then evaluate quality, unwanted behavior, serving performance and full lifecycle cost.

By Julien Laurenceau, 3 months2026-08-06 ago
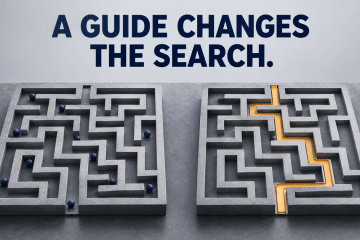
Two maze plates contrast unguided exploration with a supplied route, without a measured speedup
AI

Why Distillation Can Cut Post-Training Compute

Qwen3 reports a roughly tenfold GPU-hour difference in one post-training comparison. The result explains the value of teacher feedback, not a universal rule for total frontier-model development cost.

By Julien Laurenceau, 3 months2026-08-06 ago

Posts pagination

1 2 Next
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle