PepiteData Julien Laurenceau
  • Home
  • Services
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

Julien Laurenceau

Cartoon Spark engine lifted from a chassis beside a Sail engine, asking whether the results stay the same.
apache spark

Sail vs Spark: Architecture, Benchmarks, Dask and Numba

Sail changes the engine behind Spark Connect; Dask distributes Python work; Numba compiles numerical functions. I compare their roles, qualify Sail’s published benchmarks and outline the checks needed before a migration.
By Julien Laurenceau, 5 months2026-06-14 ago
Cartoon of an oversized GPU processing machine waiting for a single data block from a narrow feed while its billing meter keeps turning.
AI

GPU Cost Optimization: Find the Waste Before Buying More

GPU cost optimization starts with useful work, latency and paid capacity. A measurement-led review of data stalls, inference sizing, sharing and cost attribution separates removable spend from capacity gains.

By Julien Laurenceau, 5 months2026-06-14 ago
Abstract grid of glowing compute cells densely packed into reserved cluster capacity
apache spark

Spark on Kubernetes Reserves CPU It Never Uses. Here’s the Overcommit Fix.

Spark sets executor CPU requests equal to limits, so a Kubernetes cluster reserves twice the CPU it uses and refuses to schedule pending pods. Kubernetes has no native overcommit. Here is the mutating-webhook operator I use to fix it.

By Julien Laurenceau, 5 months2026-05-31 ago
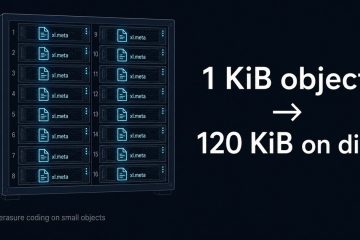
Diagram: MinIO erasure-coding storage inflation on small objects: per-drive xl.meta metadata replicated across the erasure set
data

Stop using MinIO as a NoSQL database: why S3 object stores collapse on small-file workloads

Two MinIO platforms, same root cause: used as a NoSQL store. Field notes on LIST IOPS, XFS directory limits, scanner & heal SLAs, the erasure-coding storage-efficiency inversion on small objects, and why Apache Cassandra (or Ceph) is the right answer on-prem in 2026.

By Julien Laurenceau, 6 months2026-05-17 ago
data

When the Lakehouse Works, but the Operating Model Breaks… Especially On-Premises

Note: This article was inspired by a LinkedIn post by Can Sinan A. on the hidden operational cost of an Iceberg migration, especially when governance moves from one access-control plane to several layers: catalog, storage and engine configuration Introduction Many organizations are modernizing their data platforms with lakehouse architectures, and Read more

By Julien Laurenceau, 6 months2026-05-04 ago
AI

Tesla’s .SMOL Format Shows Why Most Enterprise Data Lakes Are Architecturally Wrong

When Tesla published patent WO2024073080 describing a new file format internally called “.smol”, the headline was simple: 4x reduction in IOPS for AI training. Most people read this as a hardware story. It isn’t. It’s a data architecture story. And it exposes a structural weakness in how most enterprise data Read more

By Julien Laurenceau, 9 months2026-02-11 ago
ceph

Migrating Unmanaged OSDs to Managed OSDs in Ceph Squid

Migrating unmanaged OSDs is one of the operations I run for Ceph clients: Ceph storage consulting. If you are running Ceph Squid with a mix of managed and unmanaged OSDs, there is one thing worth stating clearly upfront: There is no in-place adoption mechanism in Squid. You cannot “import” an Read more

By Julien Laurenceau, 9 months2026-02-05 ago
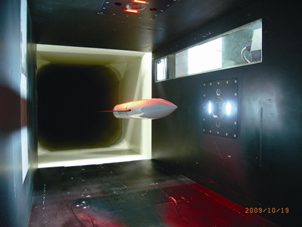
Maquette suspendue sans contact dans la veine d'essai d'une soufflerie, maintenue par sustentation magnétique
history

Pierre Laurenceau, physicien et inventeur français (ESPCI Paris)

Physicien et inventeur français de l’ESPCI Paris, actif des années 1950 aux années 1970. Un article de référence dans Physical Review Letters en 1977, six brevets français sur l’équilibrage sans contact en soufflerie et les sondes intratubulaires, et une citation comme antériorité dans un rapport du DTIC américain.

By Julien Laurenceau, 10 months2026-01-25 ago
AI

GPUs Changed Everything. Storage Is the Bottleneck Again.

GPUs are no longer the bottleneck. Data movement is. The bottleneck in AI infrastructure has moved from compute to data movement. The claim was articulated in an online talk I attended recently, and it matches what I have seen for years across very different systems: raw compute stops being the Read more

By Julien Laurenceau, 10 months2026-01-23 ago
apache spark

Apache Spark smoke tests on kubernetes

Introduction Benchmarking remains a critical (and often underestimated) tool when designing or validating large-scale data platforms. While many teams rely on synthetic workloads or production replays, standardized benchmarks still play a key role when comparing architectures, tuning clusters, or validating infrastructure choices. TPCx-HS is one of those benchmarks: designed to Read more

By Julien Laurenceau, 10 months2026-01-12 ago

Posts pagination

Previous 1 … 4 5 6 Next
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle