Pepitedata
  • Home
  • Services
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

disaster recovery

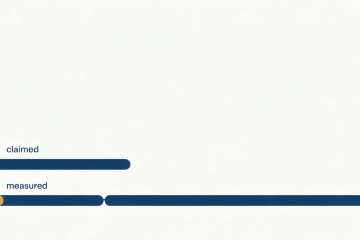
Two bars comparing a short claimed recovery duration with a far longer measured one interrupted by a waiting gap
data

Data Platform Resilience: RTO, RPO and Replication in Practice

A DR document states minutes and megabytes. Replication architecture delivers a convergence time, a single-copy window and a failed tail. This guide maps what actually decides your RTO and RPO.
By Julien Laurenceau, 5 days2026-09-30 ago
A paper cutout server rack beside a real rack, with a stopwatch between them
data

RTO and RPO for Data Platforms: Test the Recovery Path

RTO and RPO are measurable recovery objectives, not labels on an architecture diagram. Build a failure matrix and test the complete recovery path.

By Julien Laurenceau, 5 days2026-09-30 ago
Two MinIO sites locked in a closed replication loop: delete markers stamped 405 circulate endlessly between two racks, piling up instead of converging
MinIO

MinIO site replication bug: how 684 million HTTP 405s exposed the delete-marker loop

HEAD probes on delete markers answer 405 and replication counts that as success. 20M stuck versions turned the loop into 684M useless requests in 48 h.

By Julien Laurenceau, 4 weeks2026-09-06 ago
A row of mechanical counters wired into a cable trunk, with one brass counter whose output cable is cut and connects to nothing
MinIO

MinIO Replication Drops Objects Into a Counter Nobody Reads

During a MinIO replication incident three of the signals you reach for mislead you. The 405 on HeadObject is the success path, a retried 429 is invisible, and worker queue overflow logs nothing under the default priority. The counter that tracks dropped objects is incremented in four places and read in none.

By Julien Laurenceau, 1 month2026-09-04 ago
Abstract illustration of multi-site object storage replication between data centers
MinIO

MinIO Site Replication: Sync Mode Will Not Save Your RPO

MinIO site replication has no cross-site quorum, and its replication queue exists only inside the source cluster: lose that site and the un-replicated backlog is gone and un-enumerable. Sync mode costs latency without fixing that. The precise model, the RTO/RPO table, and the DR patterns that match real SLAs.

By Julien Laurenceau, 2 months2026-08-03 ago
data

Who’s Using Ceph RBD Mirroring for Kubernetes Storage in Production?

RBD mirroring in production is one of the patterns I audit and design: Ceph storage consulting. Alpha Feature in Production… Good Idea? The most promising approach, journal-based mirroring, offers near real-time replication and faster failover. However, it’s currently an alpha feature in the Ceph CSI driver and relies on rbd-nbd, Read more

By Julien Laurenceau, 10 months2025-12-15 ago
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle