object storage
Object Storage for Data Platforms at Scale
Size an object store against bytes, object metadata, request demand and maintenance time. A practical worksheet for small files, retention, erasure coding and release-channel choices.
Size an object store against bytes, object metadata, request demand and maintenance time. A practical worksheet for small files, retention, erasure coding and release-channel choices.
MinIO Community Edition has had no release since October 2025 and the repository is archived. Three CVEs will never be patched there. Here is how to assess what your cluster is actually exposed to, and where the maintained community fork fits in.
A successful source PUT does not establish a recoverable peer copy. Separate MinIO site-replication acknowledgment, persisted retry state and catch-up capacity before committing to an RTO or RPO.
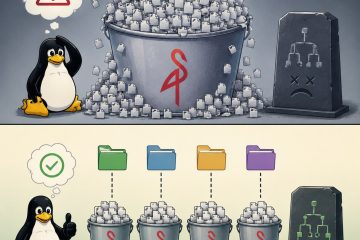
MinIO has no NameNode. It puts the namespace on XFS as real directories and xl.meta files. On Lots of Small Files that means you can exhaust inodes while df -h still looks fine, and a flat leaf can stall PUT, LIST, scanner, and ILM together. Here is the on-disk model, the inode math, and a prefix recipe that keeps XFS inside a regime you can operate.
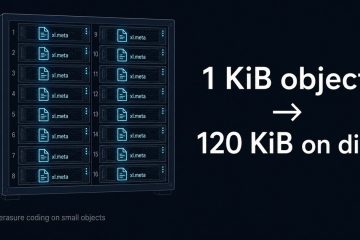
Two MinIO platforms, same root cause: used as a NoSQL store. Field notes on LIST IOPS, XFS directory limits, scanner & heal SLAs, the erasure-coding storage-efficiency inversion on small objects, and why Apache Cassandra (or Ceph) is the right answer on-prem in 2026.
Note: This article was inspired by a LinkedIn post by Can Sinan A. on the hidden operational cost of an Iceberg migration, especially when governance moves from one access-control plane to several layers: catalog, storage and engine configuration Introduction Many organizations are modernizing their data platforms with lakehouse architectures, and Read more
When Tesla published patent WO2024073080 describing a new file format internally called “.smol”, the headline was simple: 4x reduction in IOPS for AI training. Most people read this as a hardware story. It isn’t. It’s a data architecture story. And it exposes a structural weakness in how most enterprise data Read more
Migrating unmanaged OSDs is one of the operations I run for Ceph clients: Ceph storage consulting. If you are running Ceph Squid with a mix of managed and unmanaged OSDs, there is one thing worth stating clearly upfront: There is no in-place adoption mechanism in Squid. You cannot “import” an Read more
Introduction Benchmarking remains a critical (and often underestimated) tool when designing or validating large-scale data platforms. While many teams rely on synthetic workloads or production replays, standardized benchmarks still play a key role when comparing architectures, tuning clusters, or validating infrastructure choices. TPCx-HS is one of those benchmarks: designed to Read more
Hidden storage costs are one of the targets of a data platform cost optimization review. Bring the IOPS dude ! As a solutions architect working with MinIO storage solutions, I’ve seen firsthand the challenges that come with on-premises deployments using hard disk drives (HDDs). While HDDs may seem like a Read more