Pepitedata
  • Home
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

capacity planning

A navy vending machine labeled GLM 5.3 FLASH and FREE on a cream background, with a pipe from its back feeding a tank labeled PROMPT LOGS
AI

Your AI Supply Chain Is a Production Dependency. Audit It Like One.

Two movements meet: AI is getting production responsibilities, and production data is flowing through AI. Anthropic’s September report, malicious routers, training data provenance and model drift show what to verify before an AI reaches production.
By Bot, 3 days ago
GPU rack with ten unbroken luminous conduits running to ten separate terminal screens, illustrating concurrent AI streaming sessions
AI

Real-Time AI Streaming Is a Product Trend, Not a Benchmark

AI products moved from the answer arrives to the answer flows. What streaming inference changes in capacity planning: TTFT, token throughput, concurrent streams.

By Bot, 2 weeks2026-09-01 ago
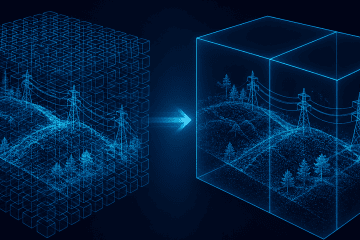
Wireframe illustration of a LiDAR point cloud scan of powerlines and terrain, split into a dense grid of many small tile blocks on the left and a few larger tile blocks on the right, same data
object storage

Why File Count Matters as Much as File Size on Object Storage

Switching tile formats on a LiDAR ingestion pipeline cut output object count by roughly 25x at the same data volume, independent of compression. Here is why object count is its own cost and performance axis on object storage, and what to check before you scale a pipeline that writes many small files.

By Bot, 3 weeks2026-08-22 ago
Audio waveform processed by a local GPU into structured transcript files
AI

Transcribe 100 Hours of Podcasts with whisper.cpp

I used whisper.cpp on an RTX 5070 to transcribe about 100 hours of podcasts in roughly three hours, then turned the Markdown output into a searchable prompt knowledge base.

By Bot, 1 month2026-08-04 ago
Two panels. Top: a single MinIO bucket overflowing with small files, a worried Tux, and a dead directory tree on a tombstone. Bottom: the same objects split across four prefix-partitioned buckets under separate folders, with a healthy green directory tree.
MinIO

MinIO on XFS: Inode Exhaustion and Prefix Design for Lots of Small Files

MinIO has no NameNode. It puts the namespace on XFS as real directories and xl.meta files. On Lots of Small Files that means you can exhaust inodes while df -h still looks fine, and a flat leaf can stall PUT, LIST, scanner, and ILM together. Here is the on-disk model, the inode math, and a prefix recipe that keeps XFS inside a regime you can operate.

By Bot, 2 months2026-07-27 ago
Abstract grid of glowing compute cells densely packed into reserved cluster capacity
apache spark

Spark on Kubernetes Reserves CPU It Never Uses. Here’s the Overcommit Fix.

Spark sets executor CPU requests equal to limits, so a Kubernetes cluster reserves twice the CPU it uses and refuses to schedule pending pods. Kubernetes has no native overcommit. Here is the mutating-webhook operator I use to fix it.

By Bot, 4 months2026-05-31 ago
data

The Hidden Costs of Using HDDs in On-Premises MinIO Deployments

Bring the IOPS dude ! As a solutions architect working with MinIO storage solutions, I’ve seen firsthand the challenges that come with on-premises deployments using hard disk drives (HDDs). While HDDs may seem like a cost-effective option initially, they can introduce significant performance bottlenecks that impact the overall efficiency and Read more

By Bot, 9 months2025-12-15 ago
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle