Pepitedata
  • Home
  • Services
  • Audits
  • Expert Call
  • About
  • Blog
  • Contact

cost optimization

A large server bank feeds a narrow processing gate, with work queuing before it, under the headline Bigger bill. Same bottleneck.
data

Performance and Cost Engineering for Data Platforms

A field guide to performance and cost engineering: claim-checking with the scaling and queueing laws, measurement discipline, where GPU and CPU budgets leak, and how to turn a benchmark into a hardware decision.
By Julien Laurenceau, 4 weeks2026-09-30 ago
An industrial model-output line diverts failed tasks into a reject bin while verified amber tasks reach the finished-work tray.
AI

AI Infrastructure and SRE: Running Models in Production

A field guide to running AI in production: the supply chain as a dependency, quiet failure as the default mode, the verification gate as the method, and cost per correctly solved task as the metric.

By Julien Laurenceau, 4 weeks2026-09-30 ago
The same payload volume split into a few large objects or many small objects, with an exaggerated pile of metadata tags
object storage

Object Storage for Data Platforms at Scale

Size an object store against bytes, object metadata, request demand and maintenance time. A practical worksheet for small files, retention, erasure coding and release-channel choices.

By Julien Laurenceau, 4 weeks2026-09-30 ago
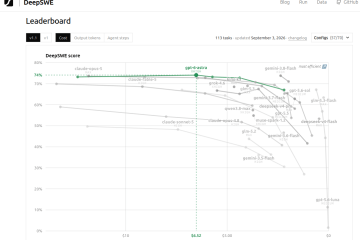
DeepSWE leaderboard: DeepSWE score against average cost per task for 113 tasks, with the cost-performance frontier highlighted and GPT-6-Astra XHIGH at .52 per task
AI

Efficiency Is Not Raw Power: Meet GPT-6-Astra and the DeepSWE Reality

GPT-6-Astra XHIGH sits alone on the DeepSWE cost-performance frontier, and an older model beats a flagship tier. Follow-up: DeepSeek V4.1 Flash hits 98% of Astra’s score at 1.4% of the cost.

By Julien Laurenceau, 2 months2026-09-06 ago
The same abstract point-cloud terrain packaged as many small tiles or a few larger containers
object storage

Why File Count Matters as Much as File Size on Object Storage

Compression, object population and request count measure different things. Compare point-cloud packaging, range reads, update costs and cleanup with an explicit synthetic sizing example.

By Julien Laurenceau, 2 months2026-08-22 ago
A large layered model transfers a signal to a smaller model across a brighter slate background.
AI

How Big Models Teach Small Models, and Why It Looks Like School

Knowledge distillation trains a student using a teacher’s examples, output scores or internal features. Compare the access each method needs, then evaluate quality, unwanted behavior, serving performance and full lifecycle cost.

By Julien Laurenceau, 3 months2026-08-06 ago
Two maze plates contrast unguided exploration with a supplied route, without a measured speedup
AI

Why Distillation Can Cut Post-Training Compute

Qwen3 reports a roughly tenfold GPU-hour difference in one post-training comparison. The result explains the value of teacher feedback, not a universal rule for total frontier-model development cost.

By Julien Laurenceau, 3 months2026-08-06 ago
AI

Model Fusion Beats the Frontier Model. The Cost Case.

OpenRouter put numbers on a pattern agent builders already use: a panel of models with a judge synthesizer beats the best single model, and a budget panel matched frontier quality at half the cost. What that means for your AI platform.

By Julien Laurenceau, 4 months2026-06-23 ago
AI

Distilling frontier reasoning into a local model: what actually works

A small coding model mocked on r/LocalLLM is actually a clean case of execution-verified distillation. Here is how the method works, when distilling a frontier model into a cheap local one pays off, and the three things the hype leaves out.

By Julien Laurenceau, 4 months2026-06-22 ago
Cartoon of an oversized GPU processing machine waiting for a single data block from a narrow feed while its billing meter keeps turning.
AI

GPU Cost Optimization: Find the Waste Before Buying More

GPU cost optimization starts with useful work, latency and paid capacity. A measurement-led review of data stalls, inference sizing, sharing and cost attribution separates removable spend from capacity gains.

By Julien Laurenceau, 4 months2026-06-14 ago

Posts pagination

1 2 Next
  • Privacy Policy
  • Mentions légales
  • CGV
  • Cookies
Hestia | Developed by ThemeIsle